Mailroom-Corpus-EDA: technical report
For the versioned corpus reference and source-license context, see Cite the dataset.
Data engineering · dataset build, audit & publishing
Summary
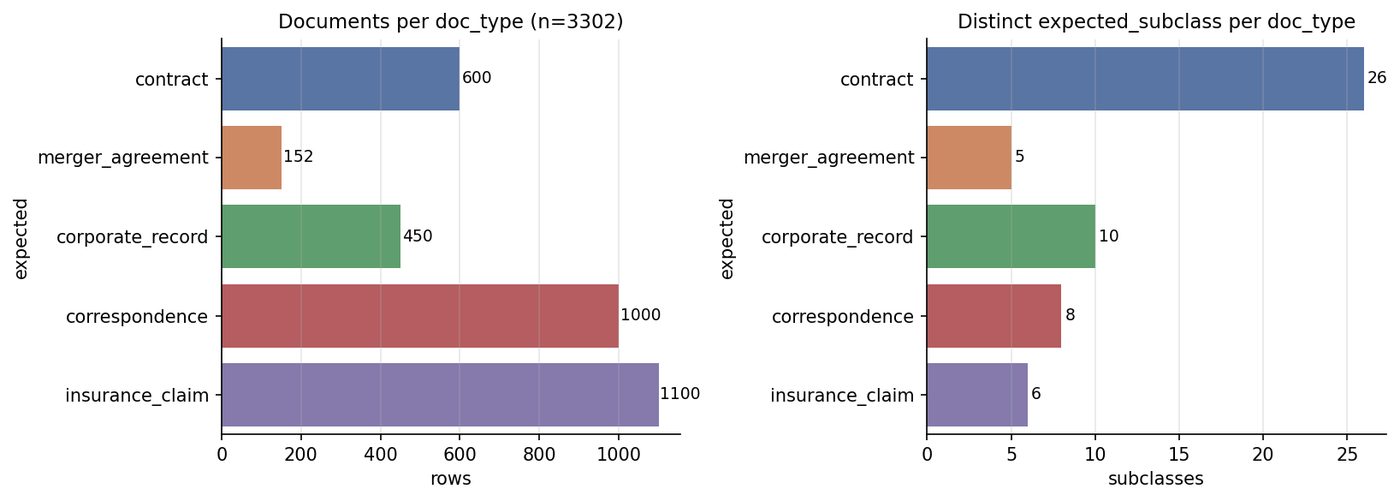
Mailroom-Corpus-EDA is the audit and publishing repository for the mailroom dataset, a corpus of 3,302 legal and insurance documents in five classes and 55 strata. The repository downloads the published dataset, checks its structure and provenance, measures its composition, draws 30 static and 18 interactive figures, audits correspondence intent coverage, and holds the helpers that build and publish new revisions to the Hugging Face Hub. This report describes the Hub tag v9.2. The current published revision is v9.3, released in November 2026: it adds corporate presence-layer labels over the same 3,302 documents and routes merger agreements to their own specialist. A v9.4 revision is staged and not yet published.
It is an evaluation and ingress-simulation corpus for the mailroom projects. It is not a training set, and the report says where that matters.
System and data
Sources
| Class | Documents | Source | Licence |
|---|---|---|---|
insurance_claim |
1,100 | CMS DE-SynPUF, GNOTHEIA, a motor-claims decision set, INSURBIAS | Apache-2.0, MIT or CC BY 4.0, depending on the source |
correspondence |
1,000 | Enron email, deduplicated (a pool of 247,523 rows) | Research use; real named individuals, so handled conservatively |
contract |
600 | CUAD v1 (509) and SEC EDGAR exhibits (91) | CC BY 4.0 and US public domain |
corporate_record |
450 | SEC EDGAR filing exhibits | US public domain |
merger_agreement |
152 | MAUD v1 | CC BY 4.0 |
I excluded three candidate insurance samples because they carry a non-commercial licence.
Configurations
| Configuration | Rows | Contents |
|---|---|---|
default (blind) |
3,302 | filename, doc_text, prompt, metadata. No label column |
ground_truth |
3,302 | Labels in a gt_fields JSON column, identity and hashes, the evaluation contract, matter and group fields: 35 top-level columns and a 34-key gt_fields union |
bundles |
50 | Synthetic multi-document families built over real anchor documents, flagged as constructed |
streams |
62 | One interleaved ingress stream with distractor documents |
fixtures |
32 | Recovery and adversarial fixtures |
Pipeline
| Phase | What it does | Output |
|---|---|---|
| P0 | Download the dataset snapshot and validate its manifest | data/parquet/ (git-ignored) |
| P1 | Structural integrity and provenance audit | reports/tables/integrity_report.json |
| P2 | Composition: strata, imbalance, provenance, metadata coverage | strata and imbalance tables |
| P3 | Static figures and tables | 30 PNGs |
| P4 | Interactive figures | 18 Plotly HTML files |
| P5 | Cast-safe JSONL and parquet staging helpers | data/staging/ |
| P6 | Correspondence intent coverage and provenance audit | reports/SUMMARY_REPORT.json |
run_all.py runs all seven phases, or any subset with --phases. The summary JSON is written only by a full run, because a subset run once overwrote the full-corpus summary with partial numbers.
The src/mailroom_eda/ package is about 21,100 lines of Python at the 6 November 2026 snapshot (revision 32d34a2). Its modules cover identity, the evaluation contract, matter grouping, the integrity audit, ground-truth quality rules, the intent backfill, token budgets, export and the Hub client.
Method
Label separation
The blind configuration is the surface a model sees, so nothing derived from a label may appear on it. An early revision still carried two integers in the blind metadata, a contract clause count and a merger annotation count. Both are functions of the hidden labels and leak a weak signal: a non-zero count says the document has labelled clauses. The v9.1 revision moved them into the ground-truth configuration. The hardened release code never restages the blind configuration, so labels cannot ride along with it.
Identity and provenance
A document id is derived from the source corpus and source filename. It does not come from a row index, the content, the split or the configuration, so it survives rebuilds and reordering. Two rows may share content, since duplicates are a legitimate mailroom scenario, but each row stays a distinct incoming artefact. Content and normalised-text SHA-256 hashes support duplicate detection and rebuild verification.
The published annotation_method records six regimes for how a label was produced:
| Regime | Rows |
|---|---|
source_native |
661 |
heuristic |
646 |
llm_zero_shot |
637 |
synthetic |
1,100 |
verified_join |
162 |
human_annotated |
96 |
The six counts add up to 3,302, one regime per row.
Correspondence intent
The canonical vocabulary is eight classes: analysis, meeting_invite, notice, other, payment_demand, press_communication, request and update. other is the explicit fallback, never null. Rows reach a label by one of four disjoint paths, recorded in intent_source:
| Path | Rows |
|---|---|
| Exact-body join against a larger Enron corpus and AESLC, by SHA-256 of the normalised, header-stripped body | 162 |
| Subject-line heuristic | 105 |
| Constrained zero-shot model pass | 637 |
| Manual | 96 |
All 1,000 correspondence rows have an intent, and 25 are flagged for review. The model pass is checkpointed, so a rerun skips rows that already have a label.
Split rule and determinism
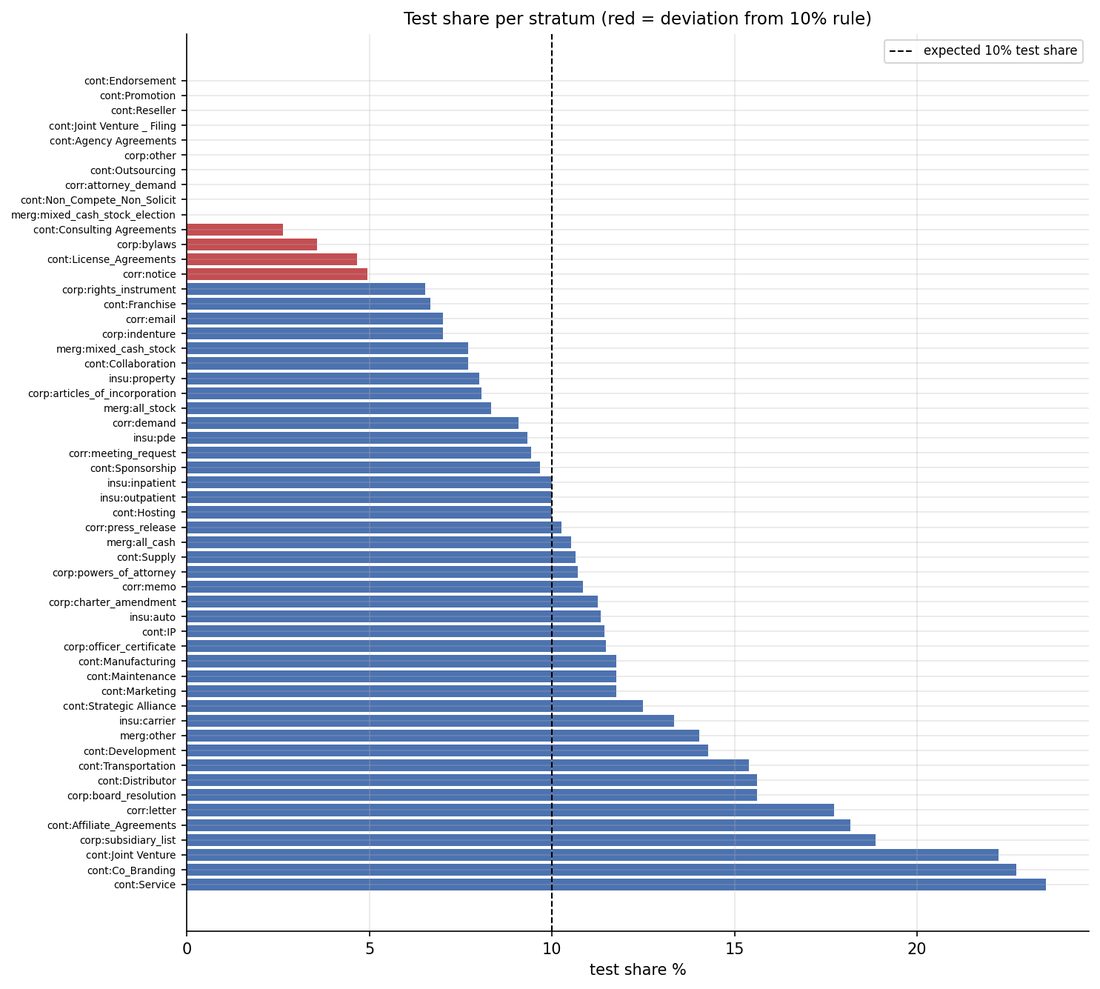
A document goes to the test set when the MD5 of its filename modulo 10 is zero. That gives 2,979 train and 323 test rows, stable across rebuilds. Random state is fixed at 42, rows are sorted before export, and a rebuild of the JSONL and parquet files is byte-identical. The interactive Plotly figures are the one exception, because each embeds a random identifier, so the committed files are treated as canonical.
Export hardening
Metadata keys are uniform and string-typed, and absence is an empty string. JSON Lines output escapes the Unicode line separators (U+2028, U+2029 and NEL), because some readers split records on them. A verification script compares a local export byte for byte against the Hub.
Results
Integrity
- The blind and ground-truth configurations agree on all 3,302 filenames.
- The split rule has zero mismatches.
- All 13,753 CUAD span annotations match the document text at their stated character offsets.
- The MAUD annotation count matches the count in the labels for all 152 merger agreements.
Composition
The largest class is 7.2 times the smallest, and the largest stratum is 557 times the smallest. One merger-agreement stratum, a mixed cash and stock election, has a single document. Ten strata have no test document and five have fewer than ten documents in total.
Text and token geometry
Token counts use a characters-divided-by-four heuristic.
| Context window | Documents that fit |
|---|---|
| 4,096 | 76.6% |
| 16,384 | 89.6% |
| 32,768 | 93.2% |
| 65,536 | 95.0% |
| 131,072 | 99.8% |
Merger agreements are the long tail, with a mean near 22,000 tokens and a maximum near 63,000. Insurance claims are short, about 690 characters on average.
Revision history
| Revision | Rows | What changed |
|---|---|---|
| v8 (frozen baseline) | 2,000 | The starting corpus, kept pinned and never deleted |
| v9 | 3,302 | Added 650 correspondence, 411 corporate records, 91 contracts and 150 insurance claims |
| v9.1 | 3,302 | Moved label-derived counts out of the blind metadata, added a per-row presence code for every label field, and added context-window bands |
| v9.2 | 3,302 | Published all six provenance regimes, removed an undocumented build-internal column, filled in relation fields on 23 heuristic rows, and corrected one audit |
| v9.3 | 3,302 | Label-only: built on the corporate relabel published as corporate-labels-v9.2.1, added presence codes for corporate entity fields, and routed the 152 merger agreements to merger_agreement_specialist |
None of v9.1, v9.2 or v9.3 added or removed a document, or changed an identifier or any document text. The changelog records zero drift. The tables and counts in this report and its appendix are for v9.2.
An audit that was wrong
After the v9.1 change moved the MAUD count to the ground-truth side, the integrity audit kept reading it from the blind metadata. It regenerated its report without error and printed a count-consistency result of 0 of 152. Nothing was wrong with the data. The audit was looking in the old place. The v9.2 revision reads the ground-truth count, restores the correct 152 of 152, and pins the case with a regression test.
Tests
I ran the test suite in a fresh environment, with the latest versions of the dependencies and not the pinned ones. That older run had 200 tests, of which 185 passed, 14 skipped and 1 failed. The current revision declares 594 def test_ functions in 26 files; that is a count, not a passing run. The 14 skipped tests need the full dataset snapshot, which run_all.py --phases P0 downloads. The 14 skipped tests need the full dataset snapshot, which run_all.py --phases P0 downloads. The failure is a contract test that reads a taxonomy file from a sibling checkout of another repository, which my environment did not have.
Limitations
- Evaluation corpus, not a training set. The 90/10 split is for reproducible sampling and is not stratified, so ten strata have no test documents.
- Imbalance. The largest stratum is 557 times the smallest, so any per-stratum score is noisy for the small ones.
- No clause annotations on 91 contracts. The SEC EDGAR exhibits were never annotated.
- Provenance mix. 637 intents come from a zero-shot model pass and 1,100 insurance labels are synthetic, so results on those rows describe the labelling method as much as the documents.
- Personal data. The Enron emails are real messages from named people.
- Token counts are a heuristic. Characters divided by four will differ from a real tokenizer.
- Continuous integration is a placeholder. The repository’s own workflow prints a message and does not run the tests, so a regression would not be caught automatically.
Reproduce
git clone https://github.com/Exios66/Mailroom-Corpus-EDA.git
cd Mailroom-Corpus-EDA
python -m venv .venv && .venv/bin/pip install -r requirements.txt pytest
.venv/bin/python run_all.py            # all seven phases
.venv/bin/python run_all.py --phases P3 P4   # figures only
.venv/bin/python -m pytest tests
Reading the public snapshot needs no token. Publishing a revision needs a Hub token.